Gemini 4 Carbon takes first place on MathArena, ending OpenAI's run at the top
The researcher-run benchmark puts Google's model at 85.4%, ahead of Claude Fable 5.2 and GPT-6.1 Sol. The top two are within each other's error bars, and the costs per problem are far apart.
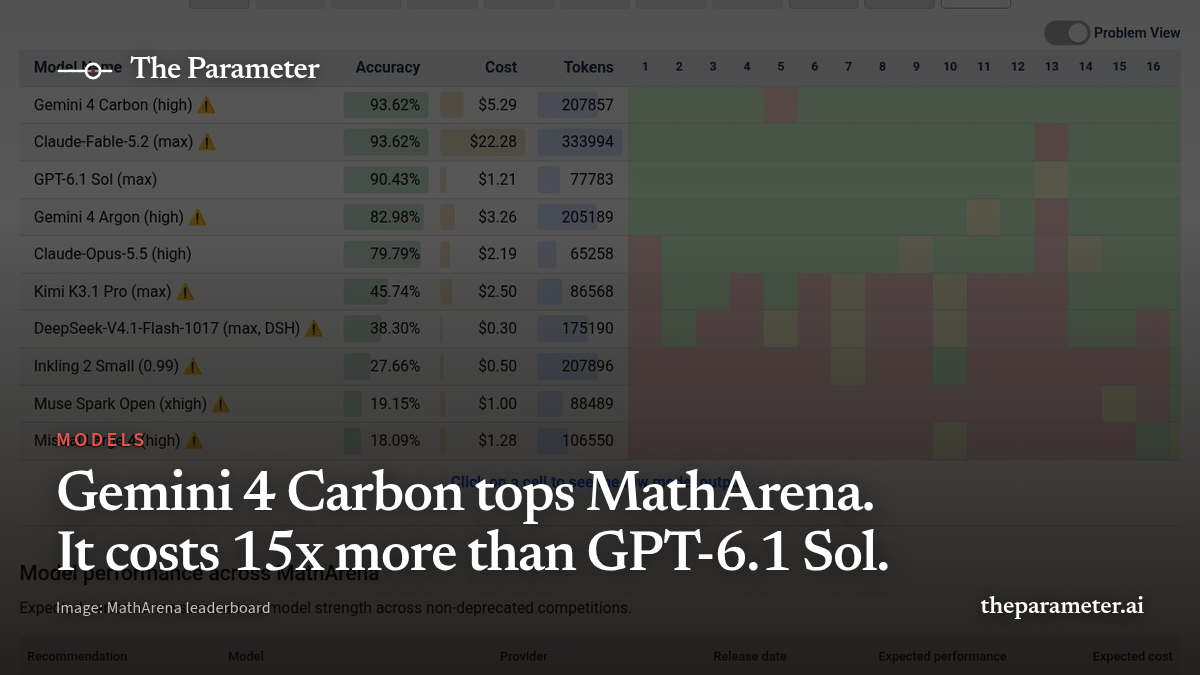
Google's Gemini 4 Carbon is now ranked first on MathArena, the math benchmark run by researchers at ETH Zurich's SRI Lab and INSAIT. MathArena added results for Carbon and Anthropic's Claude Fable 5.2 on November 13, according to the update log on its site. Carbon went to first place and OpenAI's GPT-6.1 Sol, the previous leader, fell to third.
Jasper Dekoninck, who runs the benchmark, wrote on X that "for the first time in a very long time, we have a non-OpenAI model as #1 on MathArena," as reported by ORIENS. Google itself has not announced the ranking, ORIENS noted.
The numbers
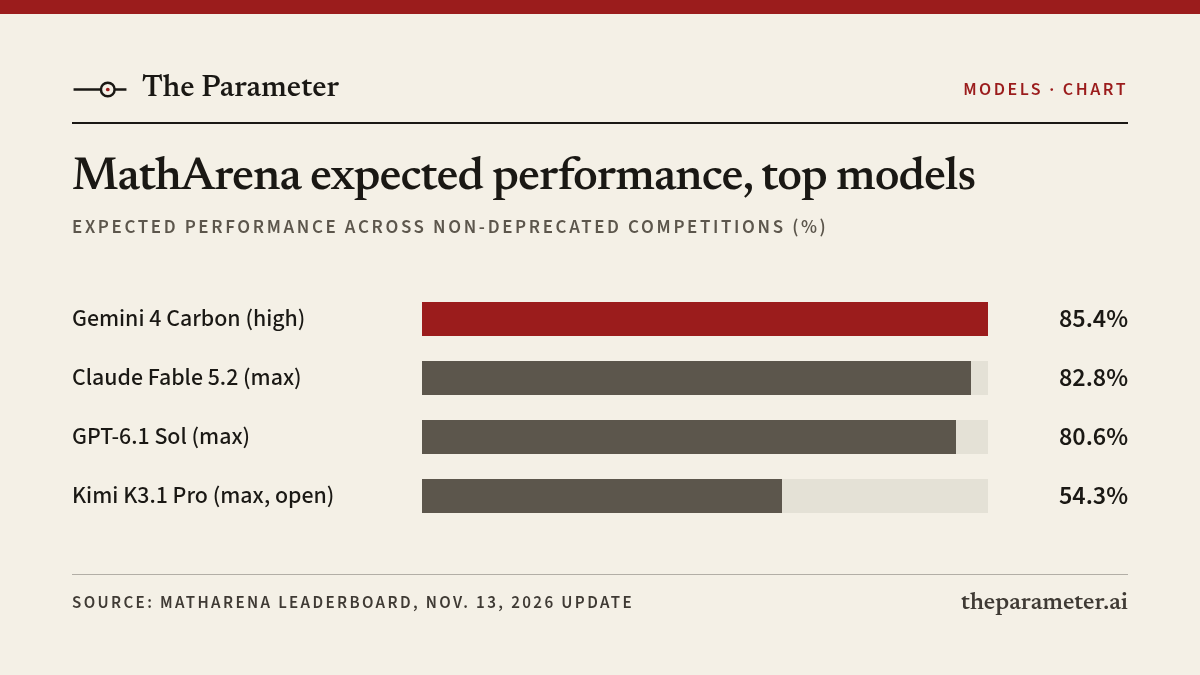
MathArena's overall table lists expected performance, an average across all questions in its current competitions:
- Gemini 4 Carbon (high): 85.4%, plus or minus 3.0 points, at an expected $15.70 per problem.
- Claude Fable 5.2 (max): 82.8%, plus or minus 5.3, at $40.20 per problem.
- GPT-6.1 Sol (max): 80.6%, plus or minus 2.7, at $1.07 per problem.
- Kimi K3.1 Pro (max) from Moonshot AI, the best model with open weights: 54.3%.
Carbon's model page shows where the lead comes from. It scores 94.28% overall on ArXivMath, where a model must rederive a precise result from a recent paper; 84.40% on BrokenArXiv, which presents a plausible but false statement and rewards models that say it is false; and 62.26% on September's ArXivLean, which requires formal proofs in the Lean language. It ranks first on all three overall.
The caveats
The first caveat is statistical. MathArena publishes confidence intervals, and Carbon's lead over Fable 5.2 is 2.6 points while Fable's interval alone is 5.3 points wide on each side. On the benchmark's own numbers, first and second are close to a tie.
The second is cost. Run at the settings MathArena tested, Carbon costs roughly 15 times as much per problem as GPT-6.1 Sol, and Fable 5.2 about 40 times as much, according to The Decoder. The Decoder also reported that Carbon's most common failure is running past the time limit, and that it almost never gives up; in one case it launched a script that ran for more than eleven hours without checking on its progress.
The third is scope. MathArena uses newly published problems so models cannot have trained on them, which makes it a useful check on contamination, but it measures math, not general ability. And models that labs have not released publicly are not on the board.
Why it matters
For teams choosing a model for math-heavy or verification work, the leaderboard now offers a real trade-off rather than a single answer: a small accuracy edge from Carbon or Fable at many times the cost, or GPT-6.1 Sol at about a dollar a problem. It is also the clearest sign yet that the top of the frontier is crowded, with three labs within a few points of each other.
Sources
- MathArena leaderboard and Gemini 4 Carbon (high) model page — MathArena (SRI Lab, ETH Zurich, and INSAIT), accessed Nov. 16, 2026
- Gemini 4 Carbon takes the MathArena crown but costs 15 times more than GPT-6.1 Sol — The Decoder, Nov. 2026
- Operator of third-party math benchmark MathArena says Gemini 4 Carbon is now No. 1 — ORIENS, Nov. 2026
The Parameter reports only what its sources support. Corrections: hello@theparameter.ai.